<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://dtinit.org/feed.xml" rel="self" type="application/atom+xml" /><link href="https://dtinit.org/" rel="alternate" type="text/html" /><updated>2026-10-13T17:33:06+00:00</updated><id>https://dtinit.org/feed.xml</id><title type="html">Data Transfer Initiative</title><subtitle>Home page for the Data Transfer Initiative, a nonprofit organization dedicated to promoting data transfers</subtitle><entry><title type="html">Portability in practice - keeping children safe online</title><link href="https://dtinit.org/blog/2026/10/13/portability-in-practice-spotlight" rel="alternate" type="text/html" title="Portability in practice - keeping children safe online" /><published>2026-10-13T00:00:00+00:00</published><updated>2026-10-13T00:00:00+00:00</updated><id>https://dtinit.org/blog/2026/10/13/portability-in-practice-spotlight</id><content type="html" xml:base="https://dtinit.org/blog/2026/10/13/portability-in-practice-spotlight"><![CDATA[<p>The most frequently asked question regarding data portability is “what are the use cases?”, and for many years the story has been mostly one-dimensional: using the same data in a different or a new place, but generally in the same sort of way. But a steady stream of new applications to our Data Trust Registry tells a different story, one of the diverse possibilities that user-led data transfers can bring. I’m excited to share these case studies here.</p>

<p>I’m starting off with a German startup called <a href="https://www.helmit.org/de">Helmit</a>, which <a href="https://dt-reg.org/registry/services/65">has Trust Level 2 in our Registry</a> (the highest level), and proudly displays the DTI Badge of Accreditation on its website. Their tools address an issue that is highly topical and certainly one that is front of mind for me – how do we keep our kids safe online?</p>

<p>Banning, or age-gating, social media for children is the most extreme policy option that is gaining traction in various countries, <a href="https://en.wikipedia.org/wiki/Online_Safety_Amendment_\(Social_Media_Minimum_Age\)_Act_2024">having been implemented in Australia already</a>, with similar policy proposals announced in other jurisdictions including <a href="https://www.gov.uk/government/publications/fact-sheet-new-rules-to-protect-children-online/fact-sheet-new-rules-to-protect-children-online">the UK</a> and <a href="https://commission.europa.eu/news-and-media/news/eu-kids-act-helping-children-navigate-safer-online-world-2026-09-17_en">the EU</a>. As a parent of two young children I understand the reasons for this tough approach, but then as a policy professional I can’t unsee the implementation challenges and potential unintended consequences.</p>

<p>Toward the other end of the interventionist spectrum, there are various parental control tools that help parents moderate and monitor their children’s online activity, many of which enable parents to read the messages their child sends and receives. As children get older, they will understandably seek ways to circumvent this privacy invasion, which will undermine the protection.</p>

<p><a href="https://www.linkedin.com/in/leonardo-benini/">Leonardo</a> and <a href="https://www.linkedin.com/in/alexander-wolters1/">Alexander</a> – Helmit’s co-founders – are pioneering a different path. Their AI-powered child safety and parental control app is designed to actively combat digital violence while preserving children’s right to privacy. This balance between online safety and privacy is made possible through data portability.</p>

<p>Through various data portability integrations, such as Meta’s Export Your Information (EYI) tool, Helmit’s users can import their children’s social media account data (with appropriate prior authorisations of course) to an AI scanning tool stored locally on device. Rather than reading through all their children’s online interactions across multiple platforms, the AI tool does it in real time and notifies the parents only when a threat has been identified – for example, when it detects signs of behavioral threat patterns, such as adult grooming tactics, coercion, or severe bullying.</p>

<p>When combined with AI technology stored locally, portability can help empower parents to keep their kids safer online without invading their personal life. I’m hopefully still a good few years away from facing this problem myself, but I am reassured to know that there are innovative companies like Helmit developing solutions that can complement the regulatory debate.</p>]]></content><author><name>Tom Fish</name></author><category term="trust-registry,trust" /><summary type="html"><![CDATA[The Data Trust Registry provides important examples of data portability in practice. German startup Helmit is focused on child safety.]]></summary></entry><entry><title type="html">Expanding AI capabilities for everyone with the Model Context Protocol</title><link href="https://dtinit.org/blog/2026/09/16/expanding-ai-capabilities-with-mcp" rel="alternate" type="text/html" title="Expanding AI capabilities for everyone with the Model Context Protocol" /><published>2026-09-16T00:00:00+00:00</published><updated>2026-09-16T00:00:00+00:00</updated><id>https://dtinit.org/blog/2026/09/16/expanding-ai-capabilities-with-mcp</id><content type="html" xml:base="https://dtinit.org/blog/2026/09/16/expanding-ai-capabilities-with-mcp"><![CDATA[<p>It’s been almost two years since Anthropic introduced the <a href="https://wikipedia.org/wiki/Model_Context_Protocol">Model Context Protocol</a>, an open standard to make third-party services and tools accessible to AI chat models.
Recently, we added MCP support to <a href="https://schemas.pub">Schemas.Pub</a>, enabling AI models to browse, search, and share public data schemas hosted on the site.
But how does it all work?</p>

<h2 id="where-ai-abilities-come-from">Where AI abilities come from</h2>
<p>Most AI chat models can only generate text.
If you send the message “What’s the weather?” directly to an AI model, the response will almost certainly not be helpful.
By default, the model doesn’t know where you are, what day it is, or any current or predicted weather conditions for any location.
It might hallucinate conditions, or hopefully reply that it can’t help with your request.
So how do chatbots like ChatGPT and Claude manage to answer these requests helpfully, not to mention edit files, search the web, and all the other things AI agents are being used for today?
The answer lies with the program used to run the model.</p>

<p>When you chat with an AI model, you use an interface like a website (chatgpt.com, claude.ai, gemini.google.com, etc) or an app on your device (Claude Code, Claude Desktop, ChatGPT Work, Codex, etc).
Most of these interfaces do much more than just forward your message to the model and show you the response.
They also inject additional text as context for your message.</p>

<p>For example, when you send “What’s the weather?” a chatbot interface might add context like, “The user is located in New York City. The date is Monday, September 14, 10:18 AM.”
Many interfaces also include a list of “tools” available, which represent software designed to be invoked by the AI model. Modern AI models have been trained to watch for available tools and respond with special text to invoke them.
Tools are advertised to the model along with other context, like in this simplified example:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>The user sent: "What's the weather?"

The user is located in New York City. The date is Monday, September 14, 10:18 AM.

You have access to tools you can use to answer the user's question:

Tool: Weather search
Description: Search for weather conditions for the provided location (city, state, country)
Use: Respond with "search_weather(&lt;location&gt;)"
</code></pre></div></div>

<p>If the model wants to use a tool, it’s been trained to respond with special text, along with any data necessary to use the tool.
In this example, it might respond with something like, “<code class="language-plaintext highlighter-rouge">&lt;invoke_tool&gt;search_weather("New York City")&lt;/invoke_tool&gt;</code>.”
The chatbot interface intercepts this response, and rather than showing it to you, performs a weather search for New York City.
The results of that search are sent back to the model, which can finally respond to your original “What’s the weather?” message based on actual weather data.</p>

<p>This is how AI models actually <em>do</em> stuff, but there’s two problems:</p>
<ul>
  <li>With so many different chatbot interfaces (we listed 7 above and barely scratched the surface!), how can third-party service providers sustainably create integrations for them all?</li>
  <li>More importantly, how can users and service providers actually add the integrations they want to use without relying on the interface developers?</li>
</ul>

<p>As we’ll see, the Model Context Protocol is designed to help with both.</p>

<h2 id="the-model-context-protocol">The Model Context Protocol</h2>
<p>The Model Context Protocol is an open standard for integrating custom tools into AI chat interfaces.
It defines a client/server relationship and communication protocol which enables AI chat interfaces to provide models with access to external services and tools.</p>

<p>Most popular chat interfaces can already act as MCP clients, including claude.ai, Claude Code, Claude Desktop, ChatGPT work, Codex, and many more.
Organizations and software developers can create MCP servers for their services to make their functionality accessible to these clients.
For example, GitHub has created <a href="https://github.com/mcp/github/github-mcp-server">an MCP server</a> to allow AI models to interact with its services.
Users can add any MCP servers they like to whichever MCP clients they use to give AI models new functionality.</p>

<p>MCP clients handle getting a list of tools and instructions for their use from MCP servers, according to communication specified by the Model Context Protocol.
The clients then include that information along with a user’s messages to the AI chat models, just as they would with the “weather search” tool in the previous example.
If the MCP client detects an invocation, it again communicates with the MCP server according to the MCP specification.
When the server recieves the request, it runs whatever code the server’s developers wrote for the requested tool, and returns some response back the the MCP client.
That response is usually sent back to the model, just like in our weather example.
MCP even defines optional authentication methods, allowing AI models to access data and take actions using the user’s authorization.</p>

<p>Since MCP is just a protocol definition, MCP client and server developers simply need to implement their respective sides of the relationship according to the MCP specification to make their software work together.
Offical code libraries exist to aid developers in making their software compatible with MCP.
During our development of the <a href="https://schemas.pub/docs/mcp">Schemas.Pub MCP server</a>, these libraries allowed us to mostly skip thinking about the details of the protocol and instead spend our time on the actual functionality we wanted to make accessible to AI.</p>

<h2 id="mcp-and-personal-data">MCP and personal data</h2>

<p>While our work adding MCP support to Schemas.Pub focused on public data, the experience helps us understand MCP’s potential for personal data.
Companies have already added support for managing personal data through MCP, and we’re especially interested in exploring if MCP can facilitate personal data portability between services.
It may be possible to transfer personal data between services by connecting AI agents to the services’ MCP servers, then instructing the agents to copy data from one service to another.</p>

<p>That said, providing AI agents with personal data management capabilities also involves privacy and safety considerations.
It may add AI service providers as another party with access to personal data.
Additionally, AI agents have potential to mishandle personal data, especially if influenced by malicious attacks such as prompt injection.
As MCP adoption increases, navigating these risks will be essential to ensuring the technology empowers users without compromising the privacy and security of their personal data.</p>

<hr />

<p>The Model Context Protocol is an example of the power of open standards.
MCP enables independent developers to build interoperable software which gives users the freedom to extend AI model functionality through the interfaces and services they choose.
This aligns well with our <a href="https://dtinit.org/ai">fourth guiding principle for AI</a> calling for “open processes” when AI services communicate with other services.</p>

<p>We wanted to help empower AI-assisted users who may not have coding experience to take advantage of the portable data schemas on Schemas.Pub.
By supporting MCP, we only had to write one AI integration, which saved us a significant amount of time.
And yet, our single integration serves the maximum number of AI chat interfaces we could practically support, meaning users get to choose whichever compatible client they like.
This exemplifies how open standards like the Model Context Protocol can be beneficial for everyone.</p>]]></content><author><name>Alex Bainter</name></author><category term="AI" /><category term="standards" /><summary type="html"><![CDATA[How should we connect AI to the services we use? Model Context Protocol is a great answer.]]></summary></entry><entry><title type="html">Launching the W3C Community Group for Browser Data Portability</title><link href="https://dtinit.org/blog/2026/09/15/launching-w3c-community-group" rel="alternate" type="text/html" title="Launching the W3C Community Group for Browser Data Portability" /><published>2026-09-15T00:00:00+00:00</published><updated>2026-09-15T00:00:00+00:00</updated><id>https://dtinit.org/blog/2026/09/15/launching-w3c-community-group</id><content type="html" xml:base="https://dtinit.org/blog/2026/09/15/launching-w3c-community-group"><![CDATA[<p>Back in April, <a href="https://dtinit.org/blog/2026/04/14/web-browsers-data-portability-patchwork">I wrote about the data portability patchwork</a> that web browser users have to navigate when they switch to a new browser. While far from seamless, web browsers offer a compelling case study: when portability works, it empowers user choice and fosters dynamic competition.</p>

<p>Following that post, I continued further down the rabbit hole. I spoke with experts across the ecosystem to test a simple ambition: could we bring the sector together to define what “good” actually looks like for the user. The feedback has been remarkably consistent and supportive:</p>

<p><strong><em>“Don’t reinvent the wheel – this is precisely what the W3C is there for.”</em></strong></p>

<p>As someone with a policy background rather than a technical one, I’ll admit the prospect of engaging the W3C is a little daunting. I have worried that I wouldn’t be welcomed by the community as I don’t speak Python or Java, and that I could become bogged down by the institutional processes. Neither of these worries were well founded (so far at least!).</p>

<p>With thanks to friends from the web community that have been supporting me – I won’t name them but they know who they are – I’ve officially submitted a proposal to establish the first <strong>W3C Community Group for Browser Data Portability</strong>.</p>

<p>My primary goal for the group is to build consensus among browser implementers on what a high-quality data transfer experience looks like for users. Ultimately, we aim to publish a W3C Community Group Report establishing shared principles for import and export functionality, leading to more consistent and reliable outcomes for users across different devices, platforms, and browsers.</p>

<p>A <strong>principles-based, non-normative approach</strong> will be essential for this work. It makes no sense for me to barge into the W3C community and start dictating the precise way that all browsers should implement their user switching and data transfer journeys. Not least because this is one of the key areas that are sovereign to browsers. But also, critically, there is just too much water under the bridge, with individual product design tied to legacy architecture, and in some cases, shaped by specific regulatory obligations.</p>

<p>By building consensus on the <strong>what</strong>, we preserve the space browser implementers need to solve the <strong>how</strong> for their specific platforms and user bases.</p>

<p>If you are a browser implementer, a W3C community member, or a policy professional interested in data portability, we want your input. Check out the <a href="https://www.w3.org/community/blog/2026/09/11/proposed-group-browser-data-portability-community-group/">Community Group proposal</a>, join the conversation, and help shape what comes next.</p>

<p>See you there!</p>]]></content><author><name>Tom Fish</name></author><category term="policy" /><summary type="html"><![CDATA[If you want to help shape shared data transfer principles across browsers, you’re in luck! We have the perfect vehicle for you, in our W3C proposal.]]></summary></entry><entry><title type="html">The shifting locus of AI portability</title><link href="https://dtinit.org/blog/2026/09/01/shifting-locus-AI-portability" rel="alternate" type="text/html" title="The shifting locus of AI portability" /><published>2026-09-01T00:00:00+00:00</published><updated>2026-09-01T00:00:00+00:00</updated><id>https://dtinit.org/blog/2026/09/01/shifting-locus-AI-portability</id><content type="html" xml:base="https://dtinit.org/blog/2026/09/01/shifting-locus-AI-portability"><![CDATA[<p>Agents are all the rage in AI these days. But what, exactly, is an agent? The concept implies, well, agency given by a human to a piece of software. An agent is empowered to make decisions and take actions based on what it encounters when it uses tools that connect it to the internet and remote services. It is typically personalized to the user and directed in specific ways. And for data portability, it’s not the model but the agent that matters.</p>

<p>The fundamental AI data portability concern that has motivated me for <a href="https://dtinit.org/blog/2023/11/21/future-AI-portable">nearly three years now</a> remains: in the AI future, will people be empowered or held hostage by their personal data? In that 2023 article, I said that models would become commoditized, and thus the ability of personal data to provide a personalized experience would be a key value proposition for AI services. The context I had in mind when writing that piece was providing personal data directly to a model; thus, portability meant being able to move personal data from one model provider to another.</p>

<p>Where does personal data sit today? With agents, the locus of where and how we build infrastructure to promote empowerment through personal data may have shifted. From an architectural perspective, an agent is a model plus a harness (see <a href="https://www.langchain.com/blog/the-anatomy-of-an-agent-harness">Vivek Trivedy</a> or <a href="https://www.databricks.com/blog/ai-harness">Databricks</a>). A harness is everything except the core trained inference engine. That includes <strong>tools</strong> that execute code and run terminal commands and look up information in databases and online; <strong>memory</strong> beyond that in the current context window, including user specific preferences and an understanding of interaction history; <strong>workspace</strong> details including files, system environments, and other context; and <strong>guardrails</strong>, any policies or permissions that are meant to limit action. Harnesses both condition and load context before the model runs – context windows being the only form of input to LLM inference other than model weights – and review and modify its outputs before the user sees them.</p>

<p>Under this definition, perhaps we’ve been talking about agentic AI portability for the entirety of our time talking about AI portability! As our focus is on an individual’s personal data, which is gained through processes apart from inference and stored in some form of long-term memory (whether in the sense of a hard disk or in the sense of an AI memory), that data has always been something a bit separate from pure LLM operations. It has always been loaded into the LLM’s context window for inference by a harness structure of some form; and that combination, then, is an agent. When those functions were blurred into the service offered by the model provider, the terminology blurred similarly.</p>

<p>These terms can be used loosely in practice. For example, Claude Code is described <a href="https://code.claude.com/docs/en/how-claude-code-works">in Anthropic’s documents</a> as an agentic harness around Claude. Is it a harness or an agent? Is Claude part of the agent or something separate from it? Also, doesn’t Claude as a “pure” chatbot, as distinct from its coding tool instantiation, also include at least memory and guardrails and some level of workspace?</p>

<p><a href="https://huggingface.co/blog/agent-glossary">Hugging Face usefully broadens agents</a> into three concepts: model, harness, and scaffold. In this configuration, the scaffold is a behavior-defining layer, and the harness is an execution layer. As I see those terms, scaffolding is more tightly connected to the model from a user’s perspective, whereas harnesses are easier to view as something operating separately.</p>

<p>Another possible layer for personal data in this context is “context,” as used by DTI affiliate <a href="https://koodos.com/">Koodos Labs</a>. A user’s personal context includes not just their memories and conversation histories, but other data that is specific to their use and running instance of AI. This could be something kept separately from the model, harness, and scaffold; in theory it could be stored within one or more of them, or separately, and paged in and out as the user needs.</p>

<p>So to return to my earlier question: Where does personal data live? Where should DTI be working with service providers to build portability tools? Like the terminology, the locus for personal data portability is unclear. Chat histories are one thing; we can get a handle on that in many respects. We know where it’s stored, and we can even <a href="https://dtinit.org/blog/2024/08/26/inflection-AI-portability">build a clean schema</a> for it. But the personal data used in customizing AI agent experiences, as distinct from chat services, can be much richer and at the same time much less clear.</p>

<p>There has been some progress in portability, though it is thus far inconsistent and very incomplete. You can import and export “memory” from <a href="https://support.claude.com/en/articles/12123587-import-and-export-your-memory-from-claude">Claude</a>. You can usually download your chat histories from service providers, and some other personal data, and Google has rolled out guidance to <a href="https://gemini.google/import-memory/">import such data into Gemini</a>. Meanwhile, a mention of the value of portable personal memory <a href="https://community.openai.com/t/portable-personal-ai-identity-a-user-owned-memory-layer-for-ai-assistants/1382003">in an OpenAI Developer Community forum</a> didn’t get any traction. As Kevin Bankston at CDT wrote in June in “<a href="https://cdt.org/insights/dont-let-perfect-be-the-enemy-of-portable/">Don’t Let Perfect be the Enemy of Portable</a>,” there’s more that can be done, especially when it comes to imports.</p>

<p>Establishing clarity, transparency, and documentation into where personal data lives and how it can be accessed by other services matters, and not just for the kinds of user personal data portability that DTI works on. The frontier services aren’t just shipping models, and haven’t been for quite a long time. They’re shipping agents themselves, integrated models and harnesses with their own context and infrastructure. This integration can make data portability more challenging technically, trying to disentangle data and services; but it also makes it more tractable for regulators, who can impose rules on a single service provider and require them to figure it out. That seems more and more likely every day.</p>]]></content><author><name>Chris Riley</name></author><category term="AI" /><summary type="html"><![CDATA[In the rapidly evolving AI ecosystem, which matters more for portability, the model or the harness? One approach: follow the (personal) data.]]></summary></entry><entry><title type="html">IETF Work Related to Personal Data Portability</title><link href="https://dtinit.org/blog/2026/08/18/ietf-work-data-portability" rel="alternate" type="text/html" title="IETF Work Related to Personal Data Portability" /><published>2026-08-18T00:00:00+00:00</published><updated>2026-08-18T00:00:00+00:00</updated><id>https://dtinit.org/blog/2026/08/18/ietf-work-data-portability</id><content type="html" xml:base="https://dtinit.org/blog/2026/08/18/ietf-work-data-portability"><![CDATA[<p>I just returned from one of the thrice-yearly IETF in-person meetings. IETF standards are, sometimes quietly, a major part of data portability. This is an overview of relevant IETF work today, especially documents in active Working Groups (WGs).</p>

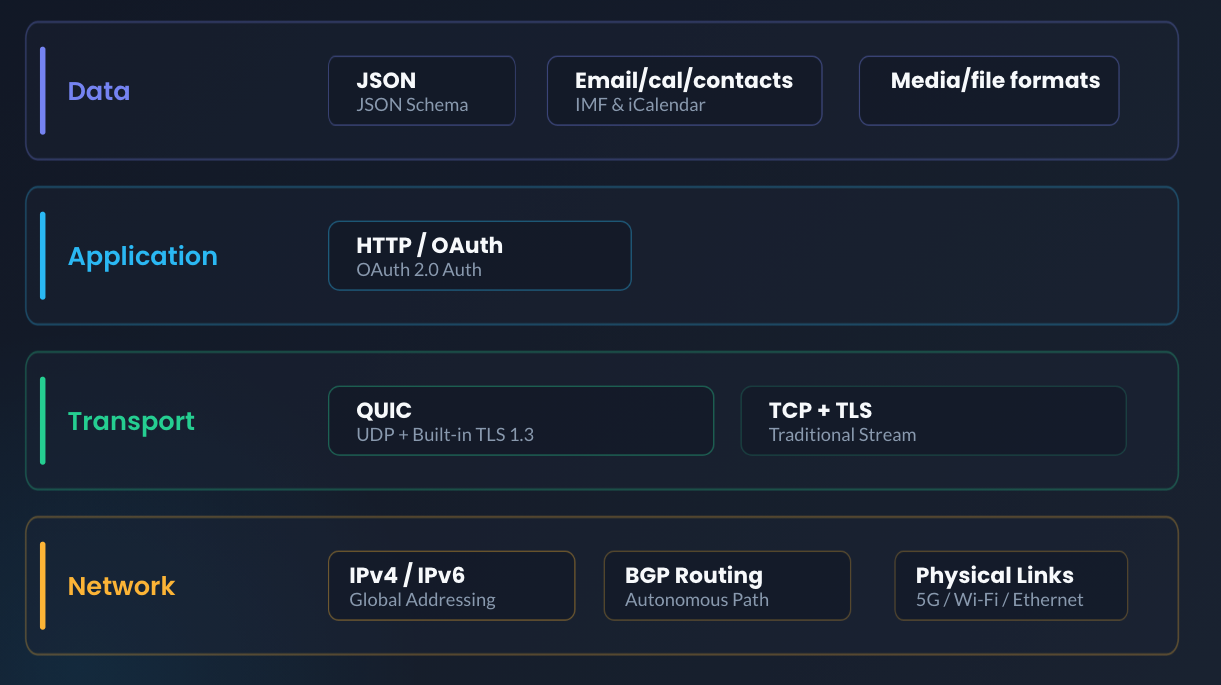
<p>The IETF is responsible for major parts of the Web API stack with <a href="https://datatracker.ietf.org/wg/http/about/">HTTP</a> and <a href="https://datatracker.ietf.org/wg/json/about/">JSON</a> the most visible, stable and widespread components. Below HTTP, the IETF is responsible for lower layers like TCP/IP and <a href="https://quicwg.org/">QUIC</a> among many others. Most portability APIs use HTTP+JSON on top of some network/transport stack, providing their own data formats for the personal data being transferred. For purposes of this piece, we won’t worry about the lower-level components and the work going on to make those components faster, more secure or more manageable.</p>

<p><img src="/images/blog/api-stack.png" alt="alt_text" title="image_tooltip" class="blog-image-med" /></p>

<p>The work that goes on at the <a href="https://datatracker.ietf.org/group/art/about/">top layer of IETF protocols</a> is often the most relevant for data portability. Some standards are only relevant for one topic (for example, if your personal data isn’t a calendar then <a href="https://datatracker.ietf.org/doc/rfc4791/">CalDAV</a> is not relevant). This article lists work relevant to implementers of:</p>

<ul>
  <li>Personal productivity servers, clients and helper apps</li>
  <li>Text, voice and video chat or conference platforms</li>
  <li>Social media feed clients or services</li>
  <li>Personal data services implementing their own APIs, data formats and authorization scopes</li>
</ul>

<p>Some work is general-interest, especially on OAuth, so jump ahead if your data portability subject matter doesn’t match the above list.</p>

<h1 id="updating-the-old-guard">Updating the old guard</h1>

<p>There is a family of related standards that have been used for personal data portability for decades: the IETF standards for email, events, tasks and contacts. Let’s call these the personal productivity standards, the widely deployed originals of which are:</p>

<ul>
  <li><a href="https://datatracker.ietf.org/doc/rfc9051/">IMAP</a> and <a href="https://www.rfc-editor.org/info/rfc5322/">Internet Message Format</a> for mailboxes and mail messages</li>
  <li><a href="https://datatracker.ietf.org/doc/rfc9051/">CalDAV</a> and <a href="https://datatracker.ietf.org/doc/rfc5545/">iCalendar</a> for calendars, events and tasks</li>
  <li><a href="https://datatracker.ietf.org/doc/rfc6352/">CardDAV</a> and <a href="https://datatracker.ietf.org/doc/rfc6350/">vCard</a> format for contacts</li>
</ul>

<p>Did you think of these as solutions for data portability? I’ve changed email providers by using IMAP twice, first telling an IMAP client to copy all my email to my laptop, then configuring that client to sync all that email history to a new email provider. This relies on well-established interoperability on email formats, mailboxes, and metadata like read/unread and draft/sent. Especially because there are <em>two</em> transfers and <em>three</em> storage implementations involved, these standards have to be pretty solid for all the details and oddities to be transferred correctly.</p>

<p>Alternately, some folks are comfortable providing a new email service with their old email service password. After all, the decision to upload all email history to the new service requires nearly the same trust in it anyway. Then the new service uses IMAP or JMAP to fetch email from the source service until it’s all synchronized. (There’s also the variation of using a <em>third</em> service like <a href="https://www.audriga.com/en/Migrate_now">Audriga</a> and providing credentials to both source and destination, then it can use IMAP or JMAP.)</p>

<p>CalDAV and CardDAV are used the same way, either server-to-client-to-server, or sharing access credentials so that the destination server can act as a client. The iCalendar formats are typically used in export/import data portability flows, because the data volume is more manageable.</p>

<p>These personal productivity standards are worth reviewing because of work in several groups that may affect data portability.</p>

<ul>
  <li>The <a href="https://datatracker.ietf.org/group/jmap/documents/">JMAP WG</a> is completing some refinements to a mature set of protocols and formats for accessing productivity data using HTTP and JSON. Since the Web kind of runs on HTTP and JSON these days, and JMAP was designed to unify and simplify a bunch of prior work, JMAP lowers the bar for supporting interoperability and portability for many kinds of personal data. More folks should look at <a href="https://jmap.io/">implementing JMAP</a>.</li>
  <li>In the <a href="https://datatracker.ietf.org/group/mailmaint/documents/">mailmaint WG</a>, we are working on <a href="https://datatracker.ietf.org/doc/draft-ietf-mailmaint-pdparchive/">PDPArchive</a>, a consolidated export/import format that can be used to do data transfers including mailboxes, mail, calendars, tasks, events, contacts and address books. This saves users from exporting and importing calendars and address books one by one, and adds other user experience and fidelity improvements.</li>
  <li>The mailmaint WG is also working on hooking OAuth up to IMAP/SMTP/JMAP, which is useful and relevant to data portability for a number of reasons - but this should be discussed in context of all active work on OAuth which I’ll tackle below.</li>
</ul>

<p>One more well-established personal data standard, not technically “productivity”, is Atom. Atom is described as a feed standard for clients to follow a feed like a blog or newsletter, but it’s also commonly used for the owner to move their feed content to a new system through export/import steps. Atom does not have active work but it felt incomplete not to mention it.</p>

<h1 id="oauth">OAuth</h1>

<p>Many are unsatisfied with the approaches described above for personal productivity data. Transferring data twice may be error prone, slow, and in many cases users don’t have the storage to hold all the email they’ve received for a decade or three. New providers would like to be able to make this process easier for new users by handling transfers server-to-server. But security folks are definitely not happy with sharing passwords to enable server-to-server because this gives ALL permissions to the destination (or 3rd party transfer service), not just content access. Everybody is turning to OAuth to provide scoped delegated authorization – but there are a few gaps.</p>

<p>OAuth is broadly deployed for Web services and their service partners, where a user logged into a Web service can authorize access to their data to the partner service. This works by pre-establishing a <a href="https://www.oauth.com/oauth2-servers/client-registration/client-id-secret/"><strong>client_id</strong> and <strong>client_secret</strong></a> that the Web service and partner service know, to protect the user from rogue services pretending to be trusted services. But manually established secrets don’t scale well or work well in some situations.</p>

<ol>
  <li>OAuth for client access</li>
</ol>

<p>The goal here is to use OAuth with the kind of client software we run on our laptops and phones. OAuth would seamlessly allow partial authorization rather than full account access, keep passwords even more secret, and support two-factor authentication. OAuth replacing SASL would make a service’s security surface more consistent and manageable between Web access and client access.</p>

<p>The blocker to using OAuth with user-installed copies of software is that the client_id/ client_secret solution doesn’t work across many installs. The developer of the client software can’t distribute the same client_id to all, or it would be discovered and used by hackers. Nor is it easy to prearrange client_id and client_secret and then deliver matched pairs to every client and every service those clients need to access.</p>

<p>Some solutions are being explored here:</p>
<ul>
  <li><a href="https://datatracker.ietf.org/doc/draft-ietf-mailmaint-oauth-public/">Using a fixed client_id</a> in clients without short-circuiting the protections that client_id offers in server-to-server cases</li>
  <li>Using certificates instead of secrets, like <a href="https://datatracker.ietf.org/doc/rfc9449/">DPoP</a> or <a href="https://datatracker.ietf.org/doc/draft-richer-oauth-httpsig/">DSig</a></li>
  <li><a href="https://datatracker.ietf.org/doc/rfc7591/">Dynamically</a> configuring and exchanging client_id and client_secret</li>
</ul>

<ol>
  <li>Reducing barriers to new parties requesting API access</li>
</ol>

<p>In an ideal rich and functional data portability ecosystem, a service provider would not have to go through manual applications to get a client_id and client_secret with every other service it may port data from. This is an NxN-scale operations and configuration challenge. At the same time, many more people are thinking of reducing barriers to AI services and AI agents requesting authorization for personal data access, for exactly the same NxN scale and overhead issues, so lots of folks are tackling this problem from SEVERAL different directions.</p>

<ul>
  <li><a href="https://datatracker.ietf.org/doc/rfc9449/">DPoP</a> or <a href="https://datatracker.ietf.org/doc/draft-richer-oauth-httpsig/">HTTPSIG</a> using signatures instead of client_secret</li>
  <li><a href="https://datatracker.ietf.org/doc/rfc7591/">Dynamic Client Registration Protocol</a> - still NxN shared secrets but automatically set them up</li>
  <li><a href="https://datatracker.ietf.org/doc/draft-hardt-oauth-aauth-protocol/">AAuth</a></li>
  <li>
    <p>Tying OAuth to a layer with certs:  <a href="https://datatracker.ietf.org/doc/rfc8705/">mTLS</a></p>

    <p>Some HTTP-based protocols like JMAP already support OAuth and will be able to benefit from these new extensions. Still, we’ll need some consolidation. It can get complicated if different services make different choices among all the options above.</p>
  </li>
</ul>

<ol>
  <li>Better defined scopes and permissions</li>
</ol>

<p>Again, AI services and AI agents are driving innovation and elaboration in this space. OAuth scopes are a black box, and although the resource server offering the scope can define any scope they like, and also walk the user through additional limits on the scope via Web UI, automation and interoperability are hard to do with that approach. For example, if a user wants to limit a booking agent to $1500 on a travel booking site, that choice of $1500 would have to be set manually each time and can’t be interoperably reviewed or set by tools such as agent harnesses.</p>

<ul>
  <li>OAuth <a href="https://datatracker.ietf.org/doc/rfc9396/">RAR</a> and <a href="https://datatracker.ietf.org/doc/draft-zehavi-oauth-rar-metadata/">extensions to RAR</a></li>
  <li><a href="https://datatracker.ietf.org/doc/draft-chen-oauth-agent-authz-use-cases/">Scoping and motivating</a> new work</li>
</ul>

<p>As you can see, work on OAuth is exploding.</p>

<h1 id="brand-new-work">Brand new work</h1>

<p>There is some newer work that is application specific.</p>

<p><a href="https://datatracker.ietf.org/group/vcon/documents/"><strong>VCon</strong></a> defines formats for virtual conversation transcripts and metadata. People wishing to port their conversation history from one platform to another, or wishing to make a reference archive of conversations, can use VCon.</p>

<p><a href="https://datatracker.ietf.org/group/atp/documents/"><strong>ATP</strong></a><strong>, also known as AT Proto</strong>, used by the BlueSky network, has a WG and is laying groundwork. It’s an explicit goal of the group to allow users to move their post/follow history between servers and not lose their connections (the way a Twitter user leaving Twitter would have had to). Note that in parallel W3C is working on ActivityPub with the same goal.</p>

<p><a href="https://datatracker.ietf.org/doc/rfc6120/"><strong>XMPP</strong></a> is being discussed at IETF again despite having a few years of development outside the IETF. It’s too early to say if a WG will be formed but folks may be interested in helping form one.</p>

<h1 id="things-you-wont-find">Things you won’t find…</h1>

<p>Since personal productivity data formats were established twenty years ago, despite their success, we don’t tend to see more IETF standards for personal data.</p>

<p>Why is there no access protocol for photo albums in the cloud, or playlists in the cloud?</p>

<ul>
  <li>File formats for images, videos and music are defined in other standards organizations (like the ISO for JPEG). Defining a protocol in IETF would require collaboration with folks who are used to operating elsewhere.</li>
  <li>IETF hasn’t been a great place to define data formats (e.g. for playlists). Folks seem to take semantic arguments to extremes, less willing to just accept a working proposal, even when a choice such as a field’s name just doesn’t matter that much for interop.</li>
  <li>It’s easier for implementers to host their own API. There’s a lot of consistency about using HTTP+JSON even if the data format for each photo album site is different.</li>
</ul>

<p>This is OK. The biggest barrier to interoperable data portability today is <a href="http://dtinit.org/trust">trust</a>, not data formats. It’s even more true in the last two years as AI has made it easy to use JSON data, often with the help of JSON Schema defined APIs (as Juan Cruz Viotti has pointed out, <a href="https://www.sourcemeta.com/blog/ai-only-speaks-json-schema/">AIs are very good at JSON and JSON Schema</a>). It’s easier to write or have AI write translators for slightly different photo album or music playlist formats than it is to standardize on a single format. That’s not to say we won’t see actual or defacto standards for those data types, because real stability, performance and perfection in the edge cases comes with standardization.</p>

<h1 id="takeaways">Takeaways</h1>

<ul>
  <li>Since trust is the largest barrier to a more functional data portability ecosystem, the OAuth work is important to everybody in data portability.</li>
  <li>New data format standards are more likely to be ad-hoc than IETF standards, although doors are open for folks to bring new data format standards if there is demand.</li>
  <li>AI is driving a great deal of work that will be relevant to non-AI driven personal data portability too.</li>
  <li>Personal productivity implementers who haven’t been engaged for a few years will find a pile of new work to digest.</li>
</ul>]]></content><author><name>Lisa Dusseault</name></author><category term="standards" /><summary type="html"><![CDATA[The Internet Engineering Task Force continues to shape the core of technology protocols, and thus, data transfers.]]></summary></entry><entry><title type="html">A midstride check-in on DTI</title><link href="https://dtinit.org/blog/2026/07/21/midstride-check-in" rel="alternate" type="text/html" title="A midstride check-in on DTI" /><published>2026-07-21T00:00:00+00:00</published><updated>2026-07-21T00:00:00+00:00</updated><id>https://dtinit.org/blog/2026/07/21/midstride-check-in</id><content type="html" xml:base="https://dtinit.org/blog/2026/07/21/midstride-check-in"><![CDATA[<p>DTI has been around for a few years now, and we’ve had a substantial impact on the landscape for data portability (evidence of which can be found in our annual reports for <a href="https://dtinit.org/assets/DTI-Annual-Report-2023.pdf">the past</a> <a href="https://dtinit.org/assets/DTI-Annual-Report-2024.pdf">three</a> <a href="https://dtinit.org/assets/DTI-Annual-Report-2025.pdf">years</a>). At the same time, it feels like we’ve never been more poised to drive meaningful change. So I want to reflect on where we are and where we’re going, and highlight why you should join us to help shape the future of trust and data in the age of AI.</p>

<p>We started at DTI with a two-fold mandate: build out and grow the Data Transfer Project, and work with policymakers and industry to help portability policy work in practice. To take the latter first, our policy research and engagement efforts are shaping the implementation of regulations to support an interoperable global data portability ecosystem that brings in all stakeholders and works without friction or duplication across borders. Emerging alignment between key UK and EU requirements are early signals of this vision in practice. You can read more on our <a href="https://dtinit.org/policy">new policy website page</a>!</p>

<p>Our technology efforts have a similarly clear impact. Since we’ve been stewarding DTP, it has acquired several new contributors and several big wins. It’s now fully in the public domain with clearer contribution paths. DTP includes music playlist portability which was a huge data and semantic undertaking with many wrinkles to iron out. And finally, it now has a public API interface for even broader interoperability: small companies can now interoperate with DTP server instances without needing to run it. It’s more valuable than ever to join DTP and reduce network interoperability barriers.</p>

<p>And our portfolio has grown far beyond DTP: we’ve built a toolkit for data donations to research and a schema repository, and begun digging into portability of personal data in artificial intelligence. The biggest dimension of growth is <a href="https://dtinit.org/trust">our work on trust</a>, notably our <a href="https://dt-reg.org/">Data Trust Registry</a>, entirely conceived, built and piloted in the last two years. DTR reduces unnecessary and onerous trust barriers by centering an ecosystem of shared trust criteria and verification processes. More organizations apply to join every week, connecting companies large and small to each other to unlock the trusted execution of user-initiated personal data transfers. Some use this access to deliver value for their users in customized digital experiences; others, like registry participants Supermarketer and Helmit, use it to protect people online.</p>

<p>There’s a running internet meme about how the real treasure is the friends we made along the way. That’s why all of the projects we’ve built or written have been intertwined with our network. Both DTP and DTR have brought us into regular contact with real companies solving real problems — and we help them share wins with each other, too. We work with other nonprofits, associations, academics, and businesses large and small. But the core of our community is DTI’s partners and affiliates. They are the most plugged into our policy and technology vision, and the biggest contributors to and champions of our impact.</p>

<p>What comes next for DTI? Continued success in our work means more tools, more trust, and smoother portability processes for the data ecosystem – and for individual people, more choice, more confidence, and more freedom. Our outputs, such as the Data Trust Registry, will be the foundation of many bridges – between companies large and small, between companies and agents, between agents and users, between companies and regulators. In particular, as I’ve written in <a href="https://www.techpolicy.press/building-trust-infrastructure-for-agentic-ai/">other places</a>, our work on data trust and transfers will shape key contours of the future of the AI landscape. <a href="https://dtinit.org/blog/2026/03/10/turning-point-AI-portability">We are at a key turning point</a> on this, today.</p>

<p>The data portability party is heating up. And everyone is invited. The value proposition for user-initiated personal data transfers is more apparent and more diversified than ever before. While consumers become increasingly curious and assertive about who collects their data and how, AI agents emerge to remind us once again that access to personal data is the evergreen killer feature. Only data portability can prevent these two trends from coming into conflict. The technology infrastructure is changing constantly, as are policies and practices.</p>

<p>It won’t be this dynamic forever, though, and as normative and practical lines start to solidify, it’s crucial to be at the table and not left behind. DTI is now established as the table that matters when it comes to personal data. And yet, considering the value of personal data in artificial intelligence, and the significance of AI and data in evolving regulatory landscapes, I feel like DTI’s work is just beginning. <a href="mailto:info@dtinit.org">Reach out</a> if data is as central to your agenda as it is ours.</p>]]></content><author><name>Chris Riley</name></author><category term="news" /><summary type="html"><![CDATA[DTI has been around for a few years now, yet it feels like we’ve never been more poised to drive meaningful change.]]></summary></entry><entry><title type="html">What–or whom–do you trust?</title><link href="https://dtinit.org/blog/2026/07/07/what-whom-do-you-trust" rel="alternate" type="text/html" title="What–or whom–do you trust?" /><published>2026-07-07T00:00:00+00:00</published><updated>2026-07-07T00:00:00+00:00</updated><id>https://dtinit.org/blog/2026/07/07/what-whom-do-you-trust</id><content type="html" xml:base="https://dtinit.org/blog/2026/07/07/what-whom-do-you-trust"><![CDATA[<p>Recently, I published an article with <em>Tech Policy Press</em> entitled “<a href="https://www.techpolicy.press/building-trust-infrastructure-for-agentic-ai/">Building Trust Infrastructure for Agentic AI</a>.” The piece is meant to simultaneously celebrate the openness of the burgeoning agentic AI ecosystem, while calling out the governance and especially trust gaps emerging alongside it. We haven’t yet witnessed Simon Willison’s “<a href="https://simonwillison.net/2026/Jan/8/llm-predictions-for-2026/#1-year-a-challenger-disaster-for-coding-agent-security">Challenger moment</a>”, but with reports saying 12-20% of skills on agent repositories <a href="https://thenextweb.com/news/hugging-face-clawhub-malware-ai-supply-chain">are actively malicious</a>, we are far from safe. Regulators are beginning to engage with AI, but they’re not nearly ready to address these gaps. The call to action in the piece is, more or less, to join DTI in building trustworthy infrastructure to improve trust in the agentic AI ecosystem. Today, I’m writing to shine a little more light on the “why” for this work, and how it supports DTI’s mission and aligns with our modalities of impact.</p>

<p>One theory for the value of blockchains and cryptocurrency technology was that they would eliminate the need for trust infrastructure, embedding trust in code rather than policy or promise; <a href="https://arxiv.org/html/2505.06661v1">that didn’t work in practice</a>. While immutable distributed ledgers have their time and place, there is no technosolution for trust problems of the form facing the agentic AI ecosystem today. Open source is similar, in that it can help contribute to trust by providing visibility into data policies and practices, but it is certainly no panacea here. Similarly, there’s value and security in creating sandbox environments where it is safe to run untrusted tech; but that doesn’t fit the many use cases where the value inherently requires connecting to the open internet and personal data.</p>

<p>So, what do we need? I’ll start with an assumption: trust is simultaneously both technical and sociopolitical. The technical side requires discovery, authorization, identity, and policy validation; the sociopolitical side first needs the entities performing the technical pieces to themselves be trusted, because “show your work” only goes so far when the stakes are so high; and second, needs tech that is scoped and applied correctly for the problem and context at hand.</p>

<p>Who’s tackling the technical pieces of trust? Here are some of the efforts we’re tracking, particularly in the identity and authorization direction where there is the most visible energy:</p>

<ul>
  <li><a href="https://datatracker.ietf.org/doc/draft-hardt-oauth-aauth-protocol/">The AAuth protocol</a> allows an agent provider to self-publish per-agent per-instance cryptographic identity over HTTPS.</li>
  <li><a href="https://www.aria.bar/">Aria.bar,</a> a nonprofit, operates a DNS-anchored agent identity registry.</li>
  <li><a href="https://developers.googleblog.com/announcing-the-agentic-resource-discovery-specification/">Agentic Resource Discovery</a>, led by Google, claims to be “DNS and search engine for the agentic web”.</li>
  <li>Blockchain-based projects such as <a href="https://github.com/m31527/AgentDID">AgentDID</a> and <a href="https://daic.capital/blog/web3-infrastructure-ai-agents">ERC-8004</a>, like AAuth, offer decentralized self-certification options.</li>
  <li>In Estonia, the government allows agents to get <a href="https://www.autheo.com/blog/ai-agent-official-digital-identity-estonia-web3-2026">official digital identities</a>.</li>
  <li>The <a href="https://www.linuxfoundation.org/press/linux-foundation-announces-intent-to-launch-agent-name-service-to-establish-trusted-identity-infrastructure-for-ai-agents">Agent Name Service</a> recently announced by the Linux Foundation carries a big brand name.</li>
</ul>

<p>Overall, the picture is complicated. In some cases, addressing and discovery issues are mixed up with identity; agents and services and users and providers can be conflated; and it’s often unclear who or what really needs identifying, who or what needs to be trusted (and by whom or what), and for what purpose. The umbrella label of “trust” often doesn’t keep the rain out, but rather just … leaks all the water through and spreads it around.</p>

<p>To make matters more complex, the critical target for establishing trust typically isn’t the agent, but rather the legal entity sitting behind it. Our use case for trust is personal data. If an agent is touching personal data, there is–hopefully!–a policy somewhere, adopted and enforced by an entity, that governs how it is using the data. At the very least, there is a person or company legally responsible for the compute that agent runs and the storage it lives on and uses. Find (and identify) the agent, find the entity, then find the policies and practices. Those can be reviewed to establish trust, and monitored for compliance to create accountability.</p>

<p>Looked at from this lens, the trust problem in data portability and the trust problem in agentic AI, at least with regard to the use of personal data, collapse to the same pair of factors: 1) make sure the user has authorized this action with the right level of insight; and 2) make sure the policies and practices that govern how personal data is handled are adequate. As I wrote in <em>Tech Policy Press</em>:</p>

<p><em>What, really, is different in the agentic AI context in terms of trust and the flow of personal data? Speed and reduced friction of development, deployment, and adoption is a clear change. But the abstract architectures and responsibilities are the same. Someone, person or entity, produces and ships a piece of software; that software communicates over the internet to a source of personal data; and a user authorizes the source of that data to make it available to the software, which uses it in some manner, including potentially passing it along to other software.</em></p>

<p>At DTI, we built the <a href="https://dt-reg.org/">Data Trust Registry</a> to help establish trust in data portability. When services apply to the registry, depending on the level of trust they are seeking, we verify the service provider’s identity, examine their privacy policy and security credentials, and review how they are communicating with users about their use of personal data. The resulting trust accreditation signals are reflected on the registry website, available for service providers to embed <a href="https://dtinit.org/blog/2026/06/23/launching-dti-badge">as a badge</a>, and provided through the registry’s API for integration into other services’ verification processes. While built for our core use case of data portability, given the convergence of trust challenges between classic portability and agentic AI, we believe DTR has the potential to be a very effective starting point for the infrastructure and system necessary to promote trust in the agentic AI ecosystem.</p>

<p>Our mission statement at DTI is: “Empower people by building a vibrant ecosystem for simple and secure data transfers.” Agentic AI is full of data transfers, and they can seem simple, but helping them be secure requires trust. We build data transfer tools and infrastructure, but as with anything adjacent to technical standards, the impact isn’t maximized by shipping perfect technology, but rather by bringing a community together around a shared solution. As one example of that, we recently <a href="https://www.library.cmu.edu/about/news/2026-06/data-transfer-initiative-joins-ofai">joined the Open Forum on AI</a> and are looking forward to working with them more.</p>

<p>Building community around trust infrastructure is central to the journey we’re on now, and we invite you to join us on it.</p>]]></content><author><name>Chris Riley</name></author><category term="trust-registry," /><category term="trust" /><summary type="html"><![CDATA[Trust imbues in people and policies, not software itself. It’s a complex, hard problem, and one increasingly central to our mission at DTI.]]></summary></entry><entry><title type="html">Launching the DTI Badge of Accreditation</title><link href="https://dtinit.org/blog/2026/06/23/launching-dti-badge" rel="alternate" type="text/html" title="Launching the DTI Badge of Accreditation" /><published>2026-06-23T00:00:00+00:00</published><updated>2026-06-23T00:00:00+00:00</updated><id>https://dtinit.org/blog/2026/06/23/launching-dti-badge</id><content type="html" xml:base="https://dtinit.org/blog/2026/06/23/launching-dti-badge"><![CDATA[<p>What do a dolphin, a frog, a lion, and a bunny have in common?</p>

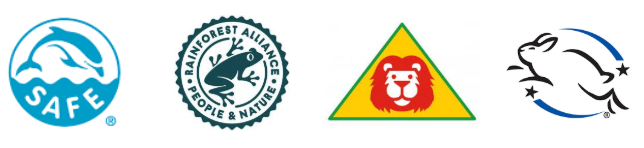
<p>As well as being mammals with a decent leap, they are all recognised logos – or trust marks – for successful certification schemes. Today DTI has launched a trust mark of our own.</p>

<figure>
  <img src="/images/blog/trust-mark-logos.png" alt="Four graphic trust marks containing imagery of animals, in order: a dolphin, a frog, a lion, and a bunny." width="650" style="display:block; margin-left:auto; margin-right:auto;" />
</figure>

<p>Each of these schemes solves an informational asymmetry problem between buyers and sellers. Where consumers see these logos on products, they gain confidence that they meet certain standards with respect to animal welfare, environmental protection, or safety. They enable producers to differentiate themselves on grounds of quality that are otherwise difficult for consumers to observe at the point of purchase.</p>

<p>There are many other accreditation and certification schemes covering a wide range of sectors, from farming, to jewelry, to forestry, to electronics. Although these schemes all solve important market failures, most are not the result of government intervention. In fact, the most successful schemes are typically run by the industry themselves, through a trade association or dedicated independent body.</p>

<p>Participation by market participants is also rarely mandated by government or regulation of any form. Whether it is a supplier of tuna, coffee, or toys, suppliers sign up to these schemes and display the badges voluntarily, because they want to send a positive signal to their customer base.</p>

<p>Businesses operating in the data transfer community have a similar informational problem. They need to be able to signal to their users, their clients, and the businesses at the other end of the transfer pipeline that they are a legitimate service that takes their data protection responsibilities seriously. In other words, that you can trust them to take care of your personal data. Just like a supermarket shopper can’t tell if dolphins were harmed in the making of a can of tuna, a user online can’t tell whether an app developer will protect their data from malicious actors, or in fact if they are one themselves.</p>

<p>We have gone part way to addressing this informational challenge through our Data Trust Registry, by verifying services against <a href="https://dt-reg.org/submission-guide/">our transparent requirements</a>, and then <a href="https://dt-reg.org/registry/">listing them publicly on the Registry</a>.</p>

<p>But that only spreads the word when someone looks at our website. Service providers have told us they want a louder signal. They want a trust mark to demonstrate their credibility. And they want it from an independent and respected body.</p>

<p>In response to this feedback, we are today launching <a href="https://dt-reg.org/badge/">the DTI Badge of Accreditation</a>, which we will issue to all services listed on the Data Trust Registry. Where approved services display it is up to them, so long as it links back to their individual listing on the Registry.</p>

<p>Get in touch if you would like to know more.</p>

<figure>
  <img src="/images/blog/dti-trust-level-1-badge.png" alt="A circular logo reading Data Trust Registry Level 1 DTI Accredited." width="400" style="display:block; margin-left:auto; margin-right:auto;" />
</figure>]]></content><author><name>Tom Fish</name></author><category term="trust-registry," /><category term="trust" /><summary type="html"><![CDATA[We are launching today the DTI Badge of Accreditation, to provide a visible signal to all services listed on the Data Trust Registry. Read more.]]></summary></entry><entry><title type="html">Our regular regulatory roundup</title><link href="https://dtinit.org/blog/2026/06/09/global-roundup-june-2026" rel="alternate" type="text/html" title="Our regular regulatory roundup" /><published>2026-06-09T00:00:00+00:00</published><updated>2026-06-09T00:00:00+00:00</updated><id>https://dtinit.org/blog/2026/06/09/global-roundup-june-2026</id><content type="html" xml:base="https://dtinit.org/blog/2026/06/09/global-roundup-june-2026"><![CDATA[<p>I often picture the global data portability ecosystem as an incomplete jigsaw puzzle. Each new portability regulation or initiative is another piece to be added. But when the pieces are designed independently in each legal jurisdiction – the EU, the UK, Japan and so on – the chances of them all automatically fitting together to form a pretty picture are low.</p>

<p>That’s where I believe DTI has an important role to play that arguably no other organisation is capable of. Our advice and global perspective can help shape the pieces so that they fit together and form a single vision, so that the ‘tabs’ from one intervention slot into the ‘blanks’ of another. Or in other words, we can help to promote international interoperability. To do that, we need to keep up to date with global developments.</p>

<p>This newsletter sets out some of the main regulatory developments for the technology sector most relevant for our audience, including highlighting the ones we are engaging with directly.</p>

<h3 id="united-kingdom"><strong>United Kingdom</strong></h3>

<p>I would of course list the UK first because I am biased. But in any case, it deserves headline billing this time around as authorities prepare to deploy the powers granted by two new Acts of Parliament: The Data (Use and Access) Act (aka “the DUAA”) and the Digital Markets, Competition and Consumers Act (aka “the DMCCA”).</p>

<ul>
  <li><strong>The DUAA</strong> gave the UK Government enabling powers to introduce Smart Data Schemes like Open Banking in other sectors of its choosing. The Department of Business and Trade has since published a <a href="https://www.gov.uk/government/publications/smart-data-strategy">Smart Data Strategy</a> in March 2026, which lists digital markets as one of the priority sectors to be pursued. In parallel, following a <a href="https://www.gov.uk/government/calls-for-evidence/smart-data-opportunities-in-digital-markets/smart-data-opportunities-in-digital-markets">call for evidence on the Smart Data opportunities in digital markets</a> last summer (to which <a href="https://dtinit.org/assets/DTI-Response-Smart-Data-Opportunities.pdf">we responded</a>), the Department for Science Innovation and Technology (DSIT) published in May 2026 a <a href="https://www.gov.uk/government/calls-for-evidence/smart-data-opportunities-in-digital-markets/outcome/smart-data-opportunities-in-digital-markets-government-response">summary and decision on next steps</a>. DSIT indicated that the Government will consult “shortly” on the overall design of a digital markets scheme.</li>
  <li><strong>Through the DMCCA</strong>, Parliament handed the Competition and Markets Authority (CMA) strong new powers to regulate large digital services where they are judged by the CMA to have Strategic Market Status (SMS). The CMA has investigations open, at different stages of development, in relation to various parts of Google’s, Apple’s, and Microsoft’s businesses. Within its investigation into Google’s General Search and Search Advertising services, which is the furthest forward, <a href="https://assets.publishing.service.gov.uk/media/6979d0915da1fd4ddea98c73/_Data_portability_conduct_requirement_v2.pdf">the CMA has consulted on Conduct Requirements</a> that would oblige Google to maintain availability for its Data Portability API in the UK, and effectively peg the UK to any further advancements in the API resulting from the EU’s implementation of the Digital Markets Act (DMA). The CMA hinted in a recent press release that this Conduct Requirement will come into force in the “coming weeks”.</li>
</ul>

<p>Also, published this week, is a <strong>consultation from DSIT</strong> on <a href="https://www.gov.uk/government/consultations/empowering-people-through-data-intermediaries/empowering-people-through-data-intermediaries#fn:1">empowering people through data intermediaries</a>. This follows a call for evidence last year that DTI responded to. In addition to consideration of legislative options for removing barriers to data intermediaries, the consultation seeks views on a non-statutory authorisation scheme, with an industry run certification process. The consultation notes that “Authorised intermediaries could be listed on a public register or permitted to display a recognised trust mark, providing a visible signal to individuals and data controllers that they meet agreed standards.”</p>

<p>DTI is engaging extensively with each of these developments, where we are pressing the importance of our <a href="https://dt-reg.org/">Data Trust Registry</a> as a key component for achieving international interoperability of smart data schemes, while also acting as a signal of credibility for listed services, which includes many data intermediaries.</p>

<p>For any UK-based readers, I encourage you to attend the <a href="https://www.smartdataforum.org/">Smart Data Forum</a> next week, where these developments will be a key topic, with DTI’s Data Trust Registry shortlisted for the Trust, Consent and Governance Award. Hopefully I will see some of you there!</p>

<h3 id="european-union"><strong>European Union</strong></h3>

<p>Although the EU is further along this regulatory journey than the UK, the implementation of targeted data portability regulations is still relatively early. There have been several developments over the past year that have moved the regulatory dialogue forwards:</p>

<ul>
  <li><strong>The DMA one year review:</strong> in 2025, the European Commission ran a consultation as part of its one year review of the DMA. <a href="https://dtinit.org/assets/DTI-Response-to-DMA-One-Year-Review.pdf">Here is our response.</a> In its follow up <a href="https://ec.europa.eu/commission/presscorner/detail/en/ip_26_914">Report</a>, the Commission rightly sought to highlight the data portability provisions in the DMA as one of its success stories, where visible progress has been made and innovative new services are starting to reach consumers. Also noteworthy was the Commission’s signal in its <a href="https://digital-markets-act.ec.europa.eu/document/788ff6d9-f0bf-47d2-80a8-611d5ee5bc51_en">Staff Working Document</a> that it will be, as a matter of priority, “monitoring whether certain AI services should be designated as virtual assistants” and therefore brought within the scope of the DMA.</li>
  <li><strong>Joint guidelines on the interplay between the DMA and the GDPR:</strong> in Q4 2025, the European Data Protection Board and the European Commission consulted on <a href="https://digital-markets-act.ec.europa.eu/consultation-joint-guidelines-interplay-between-dma-and-gdpr_en">draft joint guidelines</a> on the interplay between these two regulations. With respect to data portability, the document sought to clarify the complementary nature of DMA Article 6(9) and the GDPR Article 20, as well as setting out some more granular expectations regarding compliance with DMA Article 6(9), such as appropriate third-party onboarding procedures.</li>
  <li><strong>The Data Act:</strong> this legislation came into application in September 2025, bringing in direct transfer data portability provisions for suppliers of Internet of Things connected devices and for cloud storage providers. Despite being new, it is already facing changes through the <strong>Digital Omnibus package.</strong> Aimed at simplifying and consolidating parts of the EU’s digital regulatory framework, the package contains some tweaks to regulations that could affect existing data portability rules at the margins. For example, targeted exemptions to the Data Act’s cloud switching requirements for smaller businesses, and removing the requirement (currently in the Data Governance Act) for mandatory reporting and labelling of data intermediation services. Some concerns have been raised over the Omnibus, including by researchers over <a href="https://dsa40collaboratory.eu/open-letter-omnibus/">potential limits to data donations</a>.</li>
</ul>

<p>DTI has been frequently engaged with the European Commission on all of these topics, including responding to the consultations. We are now watching closely to see whether the DMA will be the catalyst for portability of AI ‘virtual assistant’ conversation histories, and whether the Data Act encourages more IOT companies to participate proactively in the data portability community.</p>

<h3 id="us-state-level-legislation"><strong>US State-level Legislation</strong></h3>

<p>In the United States, progress on data portability seems most likely to be steered by legislation at the State level. Utah and South Dakota have led the way, each enacting into law a “Digital Choice Act”, effective from July 2026 and July 2027 respectively. They require social media platforms to support direct data transfers to other services of all user data including the social graph. Several other States are following with similar Acts, including New York, Minnesota, South Carolina, Virginia, and California.</p>

<p>Although the legislative process still has some way to run, California’s version of the Digital Choice Act may turn out to be the most impactful. Aside from the mere fact it is California, which tends to suggest national application for tech regulation, it also includes new requirements for portability of AI contextual data such as conversation histories (as does Virginia’s). We view this as a high priority moving target, and while DTI as an organization does not engage in advocacy for or against legislation, we seek to contribute our expertise where it will help facilitate collective understanding, and are monitoring this closely.</p>

<h3 id="south-korea"><strong>South Korea</strong></h3>

<p>South Korea is one of the most advanced jurisdictions for empowering citizens to access and utilise their personal data, with its Personal Information Protection Commission (PIPC) announcing in April 2026 that citizens’ data portability rights would be extended to all major sectors of the economy.</p>

<p>Under the announced rollout timeline, individuals will be able to access their data directly from public institution websites starting in August 2026, with application to the private sector next year. As well as sectors for healthcare, telecommunications, and energy, South Korea’s MyData framework will also apply to various online platforms (above set quantitative thresholds) such as taxi-hailing services, e-commerce platforms, streaming platforms, and holiday lodging services.</p>

<h3 id="japan"><strong>Japan</strong></h3>

<p>On December 18, 2025, Japan’s long-awaited <a href="https://www.jftc.go.jp/file/en/policy_enforcement/MSCA_tentative_draft.pdf">Mobile Software Competition Act (MSCA)</a> –  also known as the Smartphone Act – officially entered into force. Enforced by the Japan Fair Trade Commission (JFTC), this ex-ante regulatory framework is focused on supporting competition within and between Apple’s and Google’s mobile ecosystems.</p>

<p>With some similarities to aspects of the EU’s DMA, the MSCA establishes explicit data portability mandates. This has prompted an expansion in the geographic availability of some existing data portability tooling, such as Apple’s Account Data Transfer API, which <a href="https://developer.apple.com/documentation/accountdatatransfer">now lists availability for users in the EU, UK and Japan</a>.</p>

<p>We have recently held conversations with the JFTC to discuss these developments, as well as to share updates on our relevant projects such as our Data Trust Registry.</p>

<h3 id="australia"><strong>Australia</strong></h3>

<p>With some parallels to the UK, Australia has two routes that may eventually lead to data portability initiatives in the digital economy:</p>

<ul>
  <li>Most immediately, there is the ongoing expansion of its Consumer Data Right (CDR) which, like the UK’s Smart Data programme, has its origins in the banking sector. It has subsequently rolled out to the energy sector, and is now expanding to non-bank lending services in July 2026. We spoke recently to the Australian Competition and Consumer Commission (ACCC) about its implementation of the CDR, highlighting some potential future overlap between our <a href="https://dt-reg.org/">Data Trust Registry</a> and the <a href="https://www.cdr.gov.au/find-a-provider?page=1">ACCC’s register of accredited data recipients</a>.</li>
  <li>Australia is also expected to introduce legislation to establish a new ex ante digital markets competition regime, leading to codes of conduct for designated digital platforms. Described by some as a hybrid between the EU’s and UK’s approaches to digital markets regulation, the requirements may well include provisions for supporting data portability.</li>
</ul>

<p>Given these developments, Australia appears to be a strong candidate for implementing data portability requirements for online platforms in the near future, though it is unclear at this stage whether it will adopt a sector wide approach via the CDR, or a more targeted approach through its planned ex ante digital competition regime.</p>

<h3 id="canada"><strong>Canada</strong></h3>

<p>Following many years of policy debate, Canada formally codified its Open Banking framework through Bill C-15, which received Royal Assent in March 2026. Critically, the Bill also amended Canada’s federal privacy law (PIPEDA) with the introduction of a new section on “Mobility of Personal Information”. This lays the foundations for Canadian authorities to introduce new data sharing frameworks in other sectors beyond banking.</p>

<p>Alongside these legislative developments, the Competition Bureau Canada published a comprehensive report in January 2026 entitled <a href="https://competition-bureau.canada.ca/en/how-we-foster-competition/education-and-outreach/publications/your-data-your-control">Your Data, Your Control</a>, with extensive references to data portability in the digital economy. It was a pleasure to chat to the team behind the report in March this year about ongoing developments in Canada and how they connect with DTI’s mission.</p>

<h3 id="india"><strong>India</strong></h3>

<p>I highlight India in this update for two significant non-developments on data portability.</p>

<p>First, the Digital Personal Data Protection Act (DPDPA) has been proceeding through a phased rollout, with full enforcement by May 2027. It is particularly noteworthy that the DPDPA, as India’s comprehensive data protection framework, does not include a GDPR-like right to data portability.</p>

<p>Second, India’s equivalent of the DMA - the Digital Competition Bill - has continued to stall, with focus shifting to further evidence gathering through a market study.</p>

<p>In contrast to some jurisdictions where data portability is a feature of privacy and competition legislation in parallel, India is not prioritising either regulatory route.</p>

<h3 id="brazil"><strong>Brazil</strong></h3>

<p>Brazil has been progressing its Digital Markets Bill designed to tackle competition challenges in digital markets, as <a href="https://www.techpolicy.press/examining-brazils-ecosystem-approach-to-digital-antitrust/">written about by Laís Martins and Megan Kirkwood</a> for Tech Policy Press in February this year. In March, lawmakers approved an “urgency motion” enabling the Bill to skip some of the slower committee stages of review.</p>

<p>If passed, the Bill will give new powers to Brazil’s competition regulator, CADE, to designate platforms as an “economic agent with systemic relevance”, with a menu of interventions then available to it including imposing requirements for continuous and real-time data portability.</p>

<p>The Bill still has several legislative hurdles to clear, so we’ll keep a watching brief.</p>

<h3 id="chile"><strong>Chile</strong></h3>

<p>The new Data Protection Act In Chile, which brings in substantial alignment with the GDPR, will officially come into full effect in December 2026. Like the GDPR, the Act includes a right to data portability, which gives the data subject “the right to have their personal data transmitted directly from controller to controller where technically possible.” As has been the case in Europe, the final three words of that quote are likely to be impactful.</p>

<p>Get in touch if there are some developments in your part of the world that deserve to be on the next update.</p>]]></content><author><name>Tom Fish</name></author><category term="policy" /><summary type="html"><![CDATA[Summer 2026: Sharing updates on data portability and related laws around the world.]]></summary></entry><entry><title type="html">ActivityPub and account portability</title><link href="https://dtinit.org/blog/2026/05/26/activitypub-and-account-portability" rel="alternate" type="text/html" title="ActivityPub and account portability" /><published>2026-05-26T00:00:00+00:00</published><updated>2026-05-26T00:00:00+00:00</updated><id>https://dtinit.org/blog/2026/05/26/activitypub-and-account-portability</id><content type="html" xml:base="https://dtinit.org/blog/2026/05/26/activitypub-and-account-portability"><![CDATA[<p>The <a href="https://jointhefediverse.net/?lang=en-us">Fediverse</a> (Mastodon and other connected servers supporting ActivityPub) was designed to be a social network running on many independent servers, allowing individuals to participate in online social life without being tied to a platform. This foundational promise, however, remains incomplete without true <strong>account portability</strong> to give users the freedom to move accounts.</p>

<p>A social account can be used to maintain friendships, collaborate professionally, pursue hobbies, share information, promote one’s preferred policies or politicians, and so much more.   All of the posts and replies in a social account build a very personal history, holding years of images, messages, memories, relationships, and a sense of evolving identity and purpose.</p>

<p>Although the Fediverse offers choice of where to create an account (like email does) and still connect, every account must live on a server, and that server is not permanent. Often hosted by a friend or former colleague, one’s Fediverse server can be shut down in an orderly way, change policies, <a href="https://fediversereport.com/defederation/">defederate</a> from other servers, <a href="https://tweaking.thebad.space/about">be defederated</a>, or simply suddenly disappear. If these server changes prompt a user to move their account, they face the difficult reality that their posts, followers, and entire digital social life may not move with them.</p>

<p>For the Fediverse’s freedom from centralized control to continue to work in a constantly moving world, Fediverse account portability cannot be an afterthought; it must be a first-class, foundational capability. Users need a reliable, non-workaround solution to move their content, accounts, and relationships from one server to another.</p>

<p>Fortunately, this isn’t hard, at least technically.  Since in the Fediverse servers request data from each other, most of the data requests to move an account to another server are already supported.  This interoperability is defined mostly by <strong>ActivityPub</strong>, an open standard developed by the World Wide Web Consortium (W3C). ActivityPub acts as the shared language, defining common structures for users (actors), content publication (outboxes), notifications and messages (inboxes), and social actions like following and sharing.</p>

<p>The few missing pieces for safe and reliable server-to-server account transfer require a bit of agreement on specifics:</p>

<ul>
  <li>How can the requesting server use OAuth to gain full access to private account information?  What exactly is the OAuth URL and what data access scope can be requested?</li>
  <li>How is private information conveyed? What ActivityStream collections hold private information and what are their URLs?</li>
  <li>How are references across servers handled when the object referred to moves?</li>
</ul>

<p>Answering these questions is why the <strong>LOLA Portability  (Live, On-Line Account Portability )</strong> <a href="https://swicg.github.io/activitypub-data-portability/lola.html">draft specification</a> was developed. LOLA defines a process where a destination server can request and copy account data directly from a source server, with the user’s authorization, while both systems remain online.  The specification is being developed within the W3C’s <a href="https://www.w3.org/groups/wg/social/">Social Web Working Group</a>.</p>

<p>LOLA organizes account portability into three structured phases:</p>

<ol>
  <li>
    <p><strong>Discovery and Authorization</strong><br />
The destination server confirms the source server supports portability and what its URLs are. The user is redirected to the source server to authenticate and explicitly approve the data transfer using <strong>OAuth 2.0</strong> and an appropriate scope that grants just the right permissions.</p>
  </li>
  <li>
    <p><strong>Fetching and Saving Data</strong><br />
Once authorized, the destination server requests and recreates the user’s key collections, such as posts, following lists, liked content, and block lists. Crucially, this is designed as a <strong>copy</strong>, not a destructive move, allowing the user to verify the result before making further decisions.</p>
  </li>
  <li>
    <p><strong>Testing and Finalizing Phase</strong><br />
After the copy is successful, the user can choose to notify followers of the move, redirect links to old content, and close down their old account, when they are ready.</p>
  </li>
</ol>

<p>The Data Transfer Initiative supports this work by contributing to the authoring of LOLA and of a <a href="https://github.com/dtinit/activity-pub-testbed">testbed</a> for LOLA implementers to test against. This supports our overall mission of improving the availability and functionality of data portability generally, by showcasing an architecture that works well even under the difficulties of federation, linked content, and private as well as public information. For a deeper dive, I have written the <a href="https://medium.com/@aaronaej/understanding-account-portability-in-the-fediverse-part-1-41bb3a22c877">start of a series of articles</a> on the testbed and the technical pieces of LOLA – check it out.</p>]]></content><author><name>Aarón Ayerdis Espinoza</name></author><category term="social," /><category term="standards" /><summary type="html"><![CDATA[The Fediverse lacks true account portability. A few specifics need to be worked out; the LOLA specification in W3C is taking them on.]]></summary></entry></feed>